
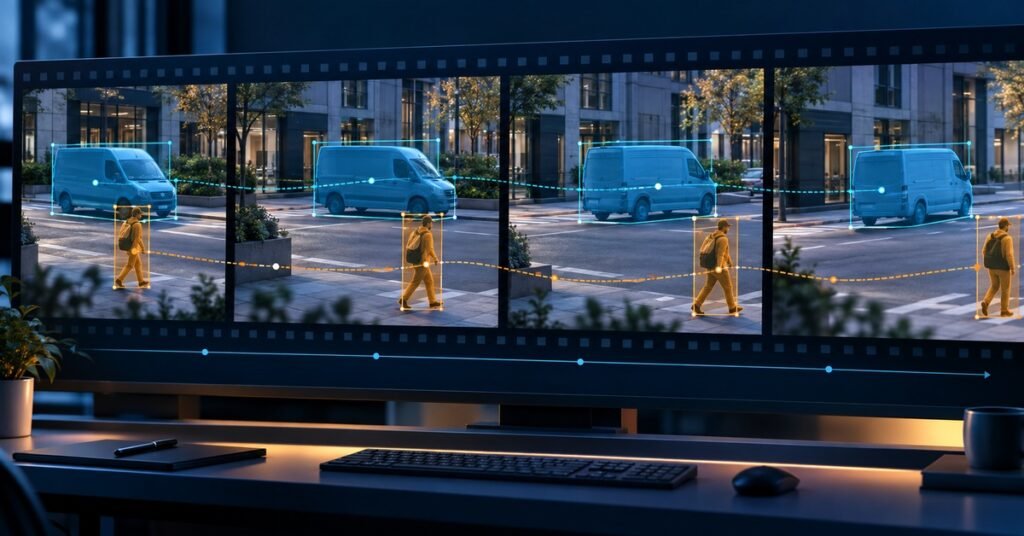
Choose video annotation services by model task, not by label count
Video annotation services turn sequences of frames into training data that preserves what happened, where it happened, and how the same object changed over time. Buyers should first define the model decision—detect an object, follow its identity, estimate a pose, segment its outline, recognize an action, or mark an event—then choose the lightest annotation that supplies that evidence. Treating video as a folder of unrelated images often removes the temporal information that made the video valuable.
The commercial decision is therefore broader than a price per frame. A usable scope defines the annotation unit, frame-selection rule, object identity, occlusion behavior, interpolation policy, ontology, output format, quality metrics, and acceptance test. It also separates production speed from accepted-output cost: inexpensive labels that need identity repair or format conversion can be more expensive than a well-designed managed workflow.
This guide helps computer vision, robotics, retail, and mobility teams compare annotation methods, vendor proposals, tools, formats, cost drivers, and pilot evidence without assuming that every frame needs the most detailed label.
Match the annotation type to the model output
Start with the prediction your system must make. The same clip can support several valid datasets, but each answers a different question.
- Frame or clip classification assigns a category to a frame, shot, or sequence: normal versus anomalous, checkout started, forklift operating, or a maneuver type. It is efficient when location is irrelevant, but boundaries between actions must be defined.
- Bounding boxes locate object instances with rectangles. They suit detection and many tracking tasks when precise outlines are unnecessary. Specify whether boxes include visible pixels only or the estimated full object during partial occlusion.
- Object tracks connect the same instance across frames with a stable identity. They support multi-object tracking, trajectory analysis, dwell time, and interaction modeling. Identity switches and broken tracks become first-class quality defects.
- Polygons or instance masks outline each object. They are useful for fine spatial reasoning, robotics, medical or industrial inspection, and scenes where overlapping objects must be separated. They cost more because boundaries change through time.
- Semantic segmentation assigns a class to every relevant pixel without necessarily preserving instance identity. Instance segmentation keeps individual objects separate. Panoptic schemes combine things and countable objects; buyers must state which representation the training pipeline expects.
- Keypoints and skeletons mark defined landmarks such as joints, tool tips, wheels, or product corners. Pose conventions, visibility states, left/right rules, and landmark order must be explicit.
- Actions, events, and temporal segments mark a start, end, actor, and sometimes a relationship: a person picks up an item, a vehicle changes lane, or equipment enters a prohibited zone. Boundary tolerance should be measured in frames or time, not left to reviewer instinct.
The Microsoft COCO paper is an authoritative reference for object detection and instance segmentation, while the BDD100K paper demonstrates how one video collection can support heterogeneous tasks including detection, lane marking, segmentation, and multi-object tracking. These references illustrate why “video annotation” is not one deliverable. A buyer must name the task and representation.
Use a layered design only when downstream value justifies it. For example, a retail project may need person tracks plus shelf-region polygons and pickup events, but not pixel masks for every person. A robotics project may require masks and keypoints on manipulable objects while background classes need only semantic regions.
Decide between frame annotation and sequence annotation
The first scope decision is whether frames are independent samples or members of a tracked sequence.
Independent frame annotation is appropriate when the model consumes still images, temporal order adds little value, or the sampling strategy deliberately seeks varied snapshots. It can simplify parallel work and export to image-oriented formats. However, sampling every nth frame without considering motion may overrepresent near-duplicates, miss brief events, or split one object into inconsistent identities.
Sequence annotation is appropriate when identity, movement, duration, transition, or interaction matters. The unit should be a complete clip or a defined shot, with rules for objects that enter, leave, disappear behind occluders, reappear, or cross a cut. Annotators need enough preceding and following context to make the same identity decision a model evaluator will expect.
Keyframe interpolation can reduce manual work in predictable motion. CVAT defines interpolation as a video mode using track objects: annotators label keyframes and intermediate shapes are linearly interpolated. Its official polygon tracking documentation also notes that polygon starting point and direction must remain consistent for useful interpolation. Automation is an accelerator, not acceptance evidence. Fast motion, deformation, camera cuts, occlusion, and scale changes need added keyframes or manual correction.
A practical sampling plan can combine:
- fixed-interval frames for broad coverage;
- scene-change or motion-based selection to reduce redundancy;
- dense labels around important events;
- risk-based oversampling of rare conditions, small objects, heavy occlusion, low light, weather, or unusual viewpoints;
- untouched holdout sequences for evaluation.
Keep related frames from one sequence in the same train, validation, or test split. Otherwise, nearly identical neighboring frames can leak visual information across splits and make evaluation look stronger than real deployment.
Make temporal consistency an acceptance requirement
A box can be correct in one frame while the track is wrong. Video QA must therefore test spatial accuracy and continuity.
Define stable identity behavior. A track ID should remain with one physical instance. When two objects cross, reviewers should inspect the approach, overlap, and separation rather than only the final frame. State when an identity can resume after occlusion and when a new track must start. Distinguish occluded (the object is present but hidden), outside (the object has left the field of view), and absent (the object is not in the scene) if the format and model use those states.
Define geometry behavior. Boxes or masks should not jitter without corresponding object or camera motion. Boundaries should follow the same inclusion rule across frames: visible pixels, amodal extent, or a class-specific convention. Interpolated shapes need review at midpoints and motion changes, not only at annotated keyframes.
Define attribute behavior. Persistent attributes such as object class, color, or equipment type should not fluctuate. Mutable attributes such as pose, visibility, activity, or traffic-light state need allowed transitions. Event labels need a documented start and end rule, for example “pickup begins at first hand-object contact and ends when the item is controlled,” with a numeric boundary tolerance.
Report quality at more than one level:
- frame-level geometry agreement, such as IoU or keypoint distance, on a stratified sample;
- class and attribute correctness;
- track completeness, fragmentation, and identity-switch counts;
- event boundary agreement and missed-event rate;
- schema and export validation;
- defect rate by sequence, annotator, class, difficulty, and production batch.
Thresholds must be task-specific. A small-object safety project may care more about missed instances than a high average overlap score. A trajectory system may accept slightly loose boxes but reject every identity switch. Require the vendor to show how disagreements are adjudicated and corrections are regression-checked.
Our guides to image annotation for computer vision and annotation guidelines that reduce rework provide companion checklists for geometry, examples, and edge cases.
Specify tools, ontology, and output format before production
Tool selection should follow the workflow. Confirm support for long videos, frame-accurate navigation, playback speed, keyframes, interpolation, track IDs, occlusion states, masks, keypoints, temporal segments, comments, audit history, role-based access, and reviewer queues. Test performance on representative resolution, codec, frame rate, and clip length; a feature list does not prove that the tool remains usable on production media.
Version the ontology and instructions together. Every label needs a definition, inclusion and exclusion rules, positive and negative examples, hierarchy, attributes, and difficult-case policy. Include rules for truncation, crowd regions, reflections, screens, shadows, tiny objects, motion blur, duplicates, cuts, and uncertain frames. Maintain a decision log when the pilot reveals a new edge case.
Design the export before the first annotation. Specify:
- coordinate convention, image origin, units, rounding, and whether boxes use width/height or two corners;
- frame numbering, timestamps, variable-frame-rate handling, and source-video checksum;
- class IDs, track IDs, annotation IDs, attribute types, and null or unknown values;
- polygon winding, mask encoding, keypoint order, visibility flags, and event intervals;
- file naming, folder structure, manifests, ontology version, tool version, and transformation history.
COCO-style JSON is common for image detection, segmentation, and keypoints, but it does not by itself settle a video identity design. Native tool formats may preserve tracks but bind the buyer to a platform. Custom JSON can fit a pipeline but increases validation and conversion work. For multi-sensor and scenario labeling, ASAM OpenLABEL provides a JSON specification for objects, frames, streams, coordinate systems, actions, events, and relations across scenes. Choose a format because the target loader can validate it, not because the name is familiar.
Ask for an export sample during procurement. Run it through the training loader, visualize randomly selected annotations, verify counts and IDs, and round-trip it only if the production workflow requires re-import. Schema-valid data can still have the wrong coordinate convention or broken temporal identity.
Understand the real cost drivers
Video annotation cost is driven by annotation events and review complexity, not raw video hours alone. A one-minute static interview and a one-minute crowded intersection have the same duration but radically different object counts and motion.
Important cost inputs include:
- total frames and effective sampled frames;
- average and peak objects per frame;
- track duration, entry and exit frequency, and occlusion density;
- geometry type: box, polygon, mask, keypoints, or combined labels;
- number of classes, attributes, and event relationships;
- video resolution, frame rate, codec, and tool playback performance;
- interpolation or model-assisted pre-label quality and the correction burden it creates;
- rare-class search, negative-example review, and long-tail coverage;
- annotator specialization, security controls, reviewer depth, adjudication, and rework;
- output conversion, validation, reporting, and change management.
Compare proposals on cost per accepted sequence or another verified unit, not only cost per frame. Require the same sample, ontology, output, QA plan, and acceptance threshold from every bidder. Ask vendors to separate setup, production, review, adjudication, and revision pricing so a low initial rate cannot hide downstream charges.
For a broader due-diligence view, use our comparison of AI data service companies to assess service scope, delivery model, and vendor fit alongside the video-specific evidence in this guide.
A worked comparison shows the issue. Vendor A proposes a low price for boxes on every tenth frame, with no identity continuity review. Vendor B prices keyframed tracks, interpolates predictable movement, reviews all occlusion transitions, and reports identity switches. If the model needs trajectories, Vendor A has not quoted a cheaper version of the same service; it has quoted a different deliverable that will require relabeling or engineering repair.
Automation can reduce repetitive drawing, but savings depend on correction time and error distribution. Measure assisted and manual workflows on the same pilot sequences. Record annotation time, review time, corrections, accepted yield, and defects by condition. Do not convert a vendor’s general productivity claim into a project forecast without sample evidence.
Run a pilot that can answer the buying decision
A useful pilot is a miniature production system, not a polished demo clip. Include normal material and difficult strata: crowded scenes, fast motion, partial and full occlusion, camera movement, blur, small targets, class ambiguity, cuts, and relevant rare events. Keep a buyer-controlled gold or adjudication set hidden from production annotators.
Before the pilot, agree on:
- model task and expected training/evaluation representation;
- source inventory, rights, security, and permitted processing;
- sequence and frame-sampling rules;
- ontology, attributes, identity, occlusion, geometry, and event-boundary rules;
- target export plus a valid example;
- QA sample, metrics, thresholds, escalation, and correction ownership;
- throughput measurement after review, not before;
- change-control and re-estimation rules.
During the pilot, measure total labor by stage, accepted annotations, error categories, identity defects, time to answer questions, guideline changes, export failures, and reviewer agreement. Segment the results by easy and hard footage. An average that blends empty frames with dense scenes is poor evidence for scale.
At pilot close, request the final annotations, validated export, issue log, corrected guideline version, decision log, QA report, and scaling assumptions. Review at least several complete sequences from start to finish. Then decide whether to approve, revise the scope, run a second focused pilot, or stop.
Use this buyer checklist:
- Does the proposed annotation directly support the model output?
- Are frame sampling and sequence boundaries explicit?
- Are track identity, occlusion, re-entry, and cut behavior defined?
- Are inclusion rules and edge cases illustrated?
- Can the tool handle production video without proxy or timing errors?
- Has the target format passed the actual training loader?
- Are geometry, class, temporal, and schema quality measured separately?
- Does pricing include review, adjudication, correction, and reporting?
- Are access, retention, and deletion controls appropriate for the footage?
- Is throughput reported as accepted output by difficulty stratum?
The strongest video annotation services proposal connects labels to the model task, preserves temporal meaning, proves export compatibility, and prices accepted quality. Share a representative video sample with Smart Language Service for annotation-method and cost recommendations; we can design the pilot, localize the ontology when needed, manage production and review, and deliver sequence-level evidence for approval.